

Search, Filters, Infrastructure
This October 2026 release is a major step in making Coreon’s graph backend more secure and scalable. With this release, the new search engines are productised, filters have been significantly improved, and term recognition gains tunable precision for different workflows.

Fast Search, Fast Term Recognition
It has been available as a tech preview already since January: This spring and summer, we revisited a couple of technological decisions to make our Multilingual Knowledge System’s search engines even faster and improve the tolerance of term recognition (so-called entity detection in more general NLP terms). An update to the tech preview from January:
- Search – the “normal” query for a word, a term:
We replaced Apache Solr with tantivy. The new engine runs directly inside the application — no separate Java process, no extra server. This results in extremely fast responses with a very low resource footprint. - Term Recognition – the analysis of a sentence to identify the terms that appear in it:
We replaced Apache Solr here, too, namely with an in-house developed letter-trie based index.
Why use a custom term recognition / entity detection algorithm instead of sticking to Apache Solr’s term-tagging capabilities? Well, there are two very different use cases to be covered:
- Translation / Terminology Checking: Detect terms in text to guarantee that the desired, approved terms are used in the source or target languages. Known from and supported within Trados Studio and memoQ translation software.
In this context, the source sentences are usually of very high quality (free of spelling errors, reviewed for style, etc). Yes, inflection and morphology need to be resolved — but that’s usually it. No surprises. - Chatbot-like interaction, spontaneous utterances: Spot terms in a user’s typed snippets to identify named entities, often for further prompting of LLMs.
In this context, the input is usually of rather mediocre quality (typos, words swapped, spaces or hyphens inserted or dropped, etc).
In both situations, the response must be extremely fast (< 200 ms), precision relatively high, i.e. not too much “noise”. However, typos and the like should be treated more tolerantly in the second case than in the first. Custom-developing a letter trie-based index resolved the two challenges we were faced with.
New in this release: the recognition API now offers match options that allow you to control this trade-off exactly. Strict matching for translation workflows where precision matters, tolerant matching for chatbot scenarios where recall matters more — configurable per request.
Of course, both search methods support performant filtering and querying within selected branches of the knowledge graph.
Overall, months of research and development went into this — to integrate Coreon as a single source of a truth, as a backbone into GenAI / LLM and other enterprise solutions. The querying software solution benefits from a live connection to Coreon, providing access to up-to-date live data, as well as Coreon’s smart search and term annotation for many languages.
Do the new search engines only work in the upcoming Coreon 2 UI — or also in Coreon 1 (the legacy UI)?
Answer: Under the hood, they work for both UIs. Specifically:
- Coreon 2 directly “goes” to the new Search (and benefits further from various performance optimisations)
- Coreon 1 as well as the CAT tool plugins using the Term Recognition continue to send calls against the legacy APIs. These are now internally routed through the new engines. We are already working on updating the plugins, so that they will soon connect directly to the new Term Recognition engine.
- The recognition endpoint is now also available via
GET, which makes it easier to integrate with CAT tools and other clients that prefer simple URL-based requests.
API: Search by Classification Code
Our Multilingual Knowledge System’s API is equipped with a new search option that allows you to find concepts by their classification code (i.e. the breadcrumb path in the knowledge graph). This is particularly useful for large, deeply structured terminologies where you already know the domain area you are looking for — for example, searching for all concepts under a specific branch like Medicine › Anatomy › Cardiovascular. The search supports both exact and prefix matching.
Term-as-you-type Improvements
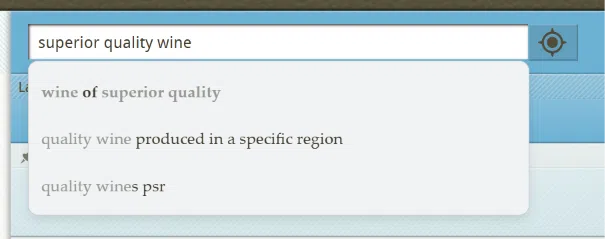
By leveraging the new Search, we also improved the algorithm of the so-called term-as-you-type behaviour (also referred to as quick search or auto-complete). In particular, it is no longer necessary for the order of the queried tokens to be identical to that of the stored term. This is particularly helpful for multiword terms.
Filters
The filtering logic of our Multilingual Knowledge System has been given significant attention in this release:
- Concept vs. Term scope works as expected: “Concept”-scoped filter rules now no longer behave like a “term”-scoped filter in the Terms list, but as intuitively expected. Concept-level filters properly restrict which concepts appear, while term-level filters act on the terms themselves.
- Concept filter applied during search: When a concept filter is active, search results now respect it correctly.
- Markup is now ignored: Filtering by terms and text values is no longer affected by formatting markup. A search for “Atlantic” finds the term regardless of whether it carries bold or italic formatting in the stored value.
- Special characters in filters: Filter conditions containing characters like
. * +are now treated as literal text, not as pattern syntax. - ‘Exists not’ works on the Terms list: The “exists not” operator for properties now properly applies when viewing the Terms list, not only for concepts.
- Sort order parity (API 2 only): The filter set index now sorts consistently between the Coreon 1 and Coreon 2 interfaces.
Import / Export
- Performance: Imports run significantly faster, especially for large datasets. Search index updates during import are now batched rather than processed one by one.
- Large files: ZIP imports are now processed as a stream, so even very large import archives no longer cause memory issues.
- Data integrity: A rare issue where property types could be corrupted during XLSX imports has been fixed.
- Export: Various performance improvements.
Faster in Various Aspects
Beyond the new search engines, this release includes many optimisations that make the everyday experience in our Multilingual Knowledge System noticeably faster:
- Terms list: Loading a page of terms now requires far fewer database queries, making the Terms list respond much faster — particularly in repositories with many languages.
- Concept navigation: Opening a concept, navigating the hierarchy, and browsing branches all benefit from new caching that avoids re-computing data that has not changed.
- Deep links survive sign in: When you follow a direct link to a concept and need to log in first, you are now taken to that concept after sign in — instead of landing on the start page.
- Limit search results (API only): A new
maxHitsparameter lets you control the number of search results returned, useful for integrations that only need the top matches.
Updates and Security Hardenings
Besides above improvements and the two new search engines, a lot of internal updates and library liftings have happened in our Multilingual Knowledge System. These accompany the recent update of the authentication module and further prepare us for an ISO 27001 certification.
- ICU-based sorting (now using established
libicu) is enabled. - A security fix ensures that administrative metadata on nested properties is no longer visible to regular users.
- Configuration changes to a repository are now also recorded in an audit trail.
- Middleware components are lifted to current versions (Ruby 3.4, Rails 8.1, Mongoid 9.0).
- Coreon XML Schema (XSD) is enhanced (to reflect access rule to MCP Server).
Enjoy these product improvements! As you may know, we are making significant progress in the beta phase of Coreon 2!
